01 / PLATFORM ENGINEERINGOperating Kubernetes at production scale.
Architecting a highly available AWS EKS platform for 50+ production microservices, with safe releases and production health as first-class concerns.
- AWS EKS
- Kubernetes
- Docker
- Service mesh
- Prometheus
- Grafana
- ELK
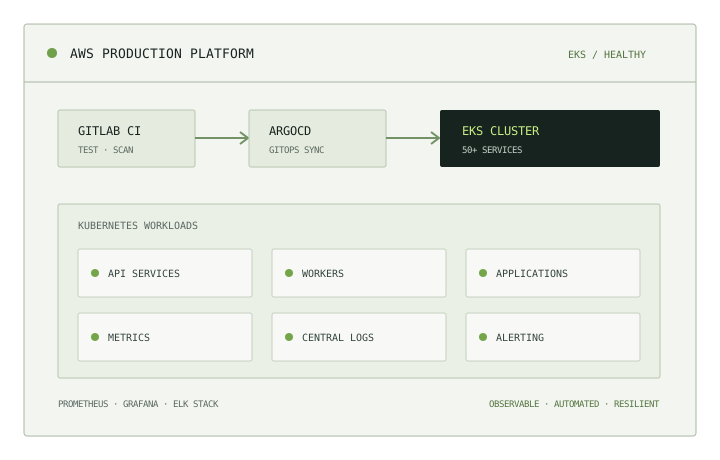
Platform scope
Designed and deployed highly available EKS clusters to orchestrate more than 50 production services. Worked with development teams on microservice and service-mesh patterns, keeping containerized workloads consistent across environments.
Container engineering
Helped optimize Docker images with multi-stage builds and security best practices. The aim was a smaller, more controlled application artifact that could move through the deployment workflow reliably.
Production signals
Established Prometheus metrics, Grafana dashboards and alerting, and ELK centralized logs to make application performance and system health visible during routine operations and incidents.
99.9%production uptime50+microservices supported
02 / DELIVERY ENGINEERINGTurning release steps into a dependable pipeline.
Building repeatable delivery paths that combine automated checks, security controls, and deployment strategies across multiple environments.
- GitLab CI/CD
- Jenkins
- ArgoCD
- Automated testing
- Security scanning
- Blue-green
- Canary
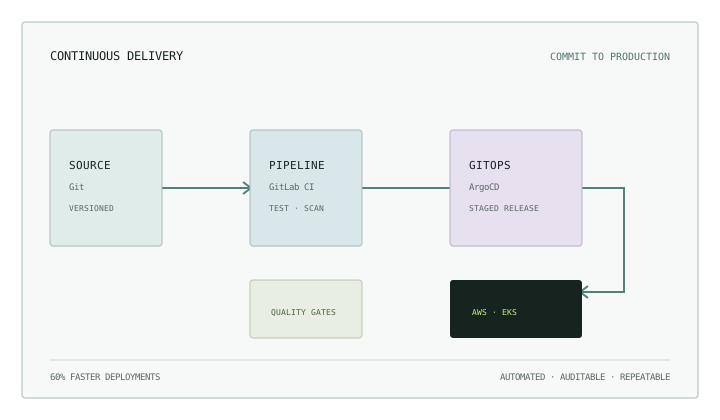
Pipeline stages
Engineered GitLab CI/CD workflows that run automated tests and security scans before promotion through development, staging, and production. Multi-stage deployments made the release path consistent rather than dependent on manual steps.
GitOps & release safety
Used ArgoCD to support GitOps deployments. Across earlier Jenkins and GitLab pipelines, added code-quality checks and vulnerability scanning, and introduced blue-green and canary strategies for zero-downtime releases and faster rollback.
Security & collaboration
Partnered with security teams to bring vulnerability scanning, compliance monitoring, and policy enforcement into CI/CD. This put checks closer to delivery instead of leaving them as a separate end-of-process handoff.
60%faster deployment time
03 / CLOUD MODERNIZATIONStandardizing infrastructure across accounts.
Modernizing legacy applications while making AWS environment provisioning repeatable across a 20+ account estate.
- AWS
- Terraform
- Ansible
- Docker
- Kubernetes
- Auto Scaling
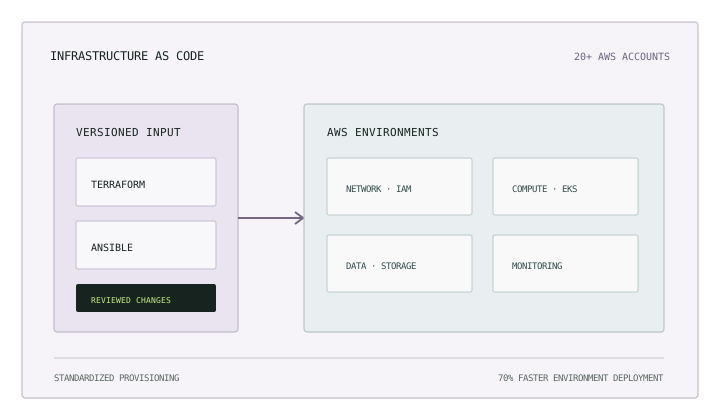
Infrastructure scope
Created reusable Terraform modules and Ansible automation for AWS networking, compute, databases, storage, serverless, and identity. The wider cloud footprint included VPC, EC2, RDS, S3, Lambda, IAM, CloudFront, and Route 53.
Application modernization
Migrated more than 15 legacy applications into Docker and Kubernetes environments. Used resource optimization and auto-scaling approaches to improve scalability while controlling cloud spend.
Repeatable delivery
Standardized provisioning and configuration across 20+ AWS accounts. Terraform and Ansible workflows reduced environment setup time and made infrastructure changes easier to review and reproduce.
15+applications modernized20+AWS accounts supported300%scalability improvement70%faster environment deployment40%infrastructure cost reduction
04 / RELIABILITY & OPERATIONSMaking systems easier to observe and recover.
Pairing observability with operational automation, incident response, and explicit recovery objectives.
- Prometheus
- Grafana
- ELK
- Python
- Bash
- AWS
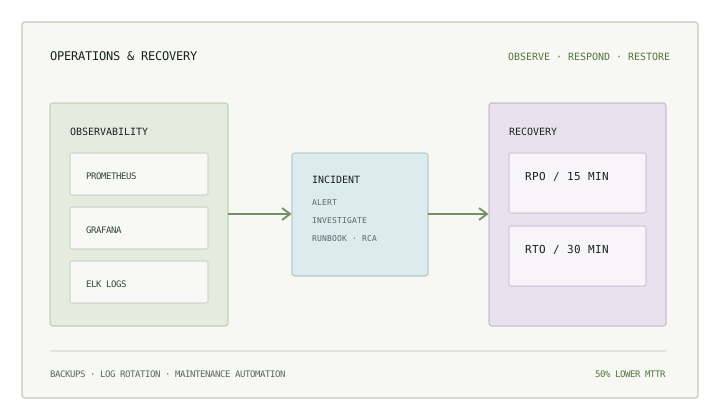
Signals & diagnosis
Built Grafana dashboards and Prometheus alerting around system and application metrics, with ELK for centralized log analysis. These shared views helped teams identify degradation and investigate incidents with better context.
Automation & response
Wrote Python and shell utilities for backups, log rotation, system maintenance, and security compliance checks. Led root-cause analysis and established runbooks and preventive actions to reduce repeat incidents.
Recovery planning
Established AWS-based backup and disaster-recovery procedures around explicit recovery objectives: a 15-minute recovery point objective and a 30-minute recovery time objective.
50%reduction in mean time to resolution15 minRPO30 minRTO
Want the full career timeline?
View experience ↗